Intelligent Document Processing
A production-ready, API-first platform for automated document extraction — from cloud to air-gapped enterprise environments.
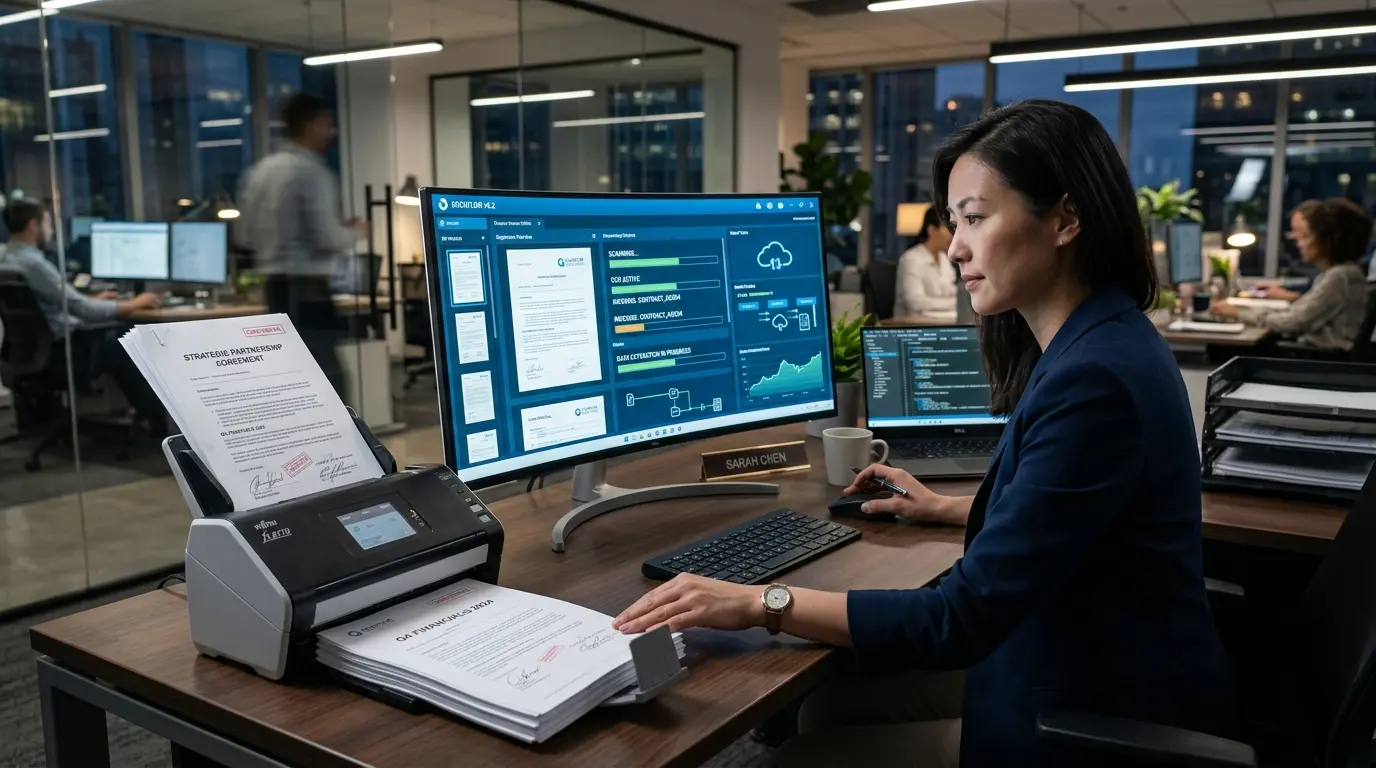
Platform Capabilities at a Glance
Multi-Format Ingestion
PDF, JPG/PNG/TIFF, Word, Excel, ZIP — digital and scanned documents, batch or real-time.
AI-Driven Extraction
OCR, layout detection, and LLM-powered field extraction for key-value pairs, tables, and complex formats.
Workflow & Validation
Configurable pipelines with human-in-the-loop QC, role-based access, and audit trail.
Integration & Output
REST API ingestion, JSON output, monitoring dashboard, and full traceability.
SaaS Deployment
Fastest Path to Go-Live
Cloud-native deployment powered by Amazon Bedrock for LLM-based extraction. Key advantage: Zero development required — configuration only.
On-Premises Deployment Options
Connected On-Prem
Application in client environment with Secure AWS Bedrock. Minimal architectural changes — same full capability as SaaS.
Air-Gapped On-Prem
Custom build with local LLM & OCR, GPU/CPU optimized. Requires local LLM deployment, custom pipelines, and hardware optimisation — scoped separately.
Custom IDP Implementation
Required for air-gapped environments, highly complex document formats, or domain-specific extraction needs such as tariffs, contracts, and insurance claims.
Detailed Scope
- Model selection & deployment (LayoutLM, Donut, LLMs)
- Prompt engineering and fine-tuning
- Custom extraction logic (multi-page, relational tables)
- Business rule validation layer
- Custom UI workflows and performance optimisation
Implementation Timeline
Deployment Model Comparison
SaaS
Connected On-Prem
Air-Gapped
Key insight: Deployment model selection directly determines scope, timeline, and investment. Align on environment constraints early to set accurate expectations.
What we cover?
Platform & Deployment
- IDP setup (Cloud or Connected On-Prem)
- Environment config, user access & roles
Document Processing
- OCR and extraction for supported types
- Pre-configured templates: Invoices, KYC, Forms
Integration
- REST API ingestion and output delivery
- Basic integration support included
Workflow & Audit
- QC human-in-the-loop interface
- Dashboard, logging, and audit trail
Executive Summary
"Our IDP platform enables rapid deployment in cloud environments with minimal effort. For enterprise on-prem or air-gapped requirements, we provide a customised implementation tailored to security and document complexity needs."
Platform is Built
Production-ready, no development needed for standard deployments.
Deployment is Flexible
Cloud, connected on-prem, or fully air-gapped — each with a clear scope.
Expectations are Clear
Capability, customisation effort, and client constraints are explicitly separated.
Ready to automate your document workflows?
Deploy our production-ready IDP platform and extract value from every document — instantly.
India
 CTD Techs Pvt. Ltd,
Kochar Bliss, 4th Floor, Guindy, Chennai, India - 600032
salesqueries@ctdtechs.ai
+91-9384699691
USA
 Connect The Health Dots,
225 Dyer Street, Providence, RI, 02903, USA
salesqueries@ctdtechs.ai
Canada
 Connect The Intelligence Dots,
BHive, 8 Nelson St W, Brampton, Ontario, L6X 1B7
salesqueries@ctdtechs.ai
+91-9150064825
Saudi Arabia
 Office 97, Bayt 7 Tower,
King Faisal Road,
Riyadh 12513
salesqueries@ctdtechs.ai